Day 3 · Wed, Sep 30, 2026
LLM Routing with Hermes
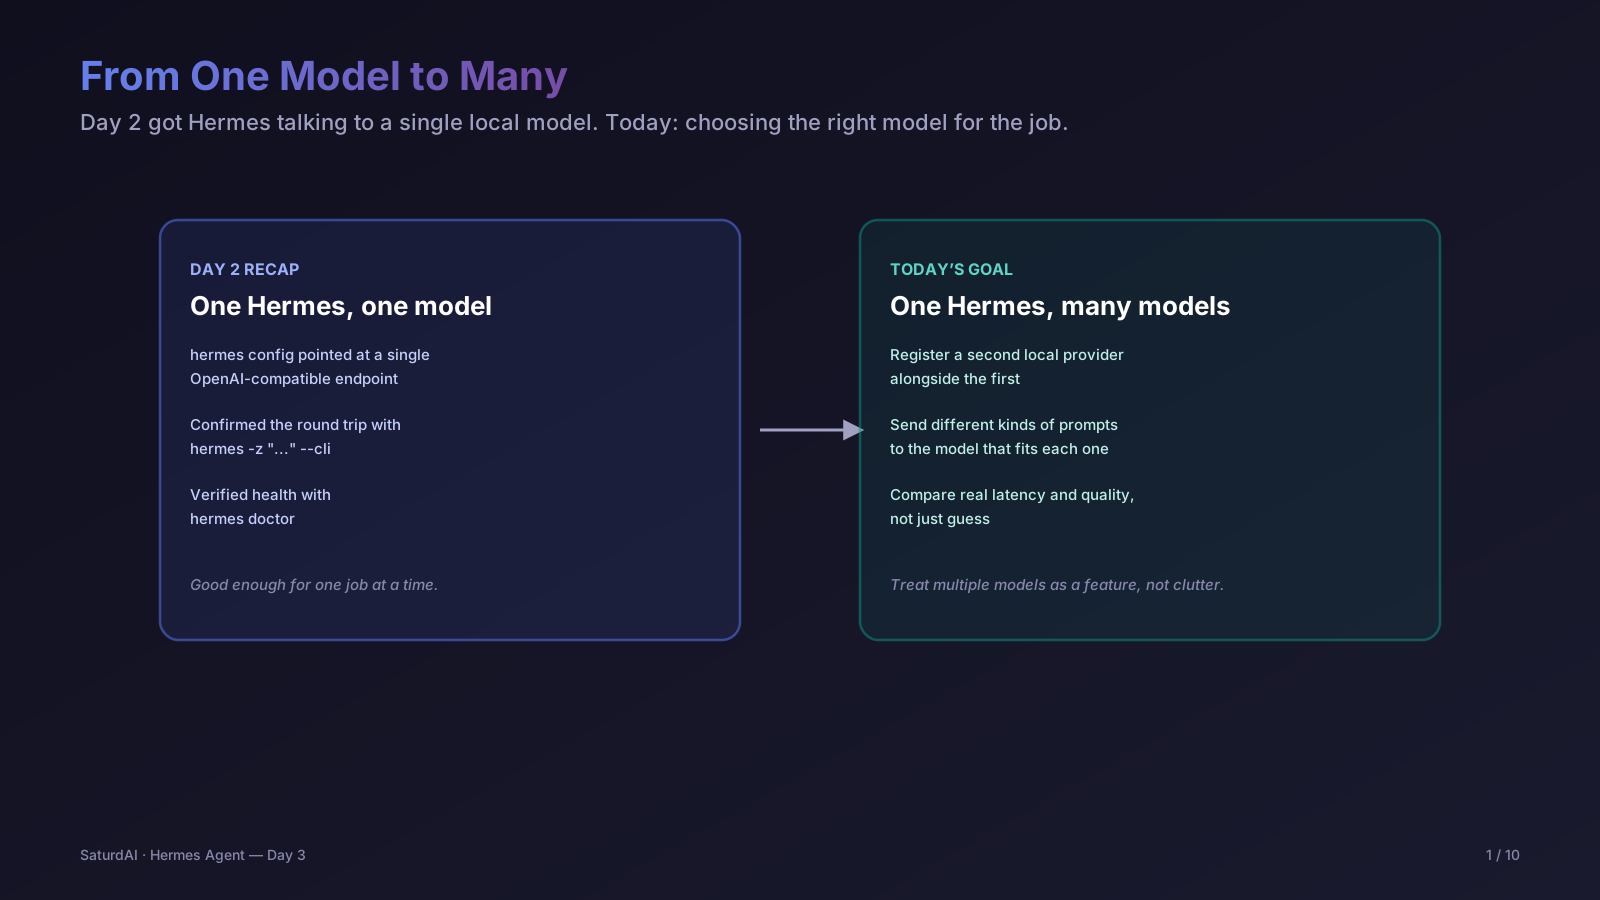
The DGX Spark's 128 GB of memory is enough to keep more than one model loaded at once — multiple 30B-parameter LLMs, or one much larger model up to roughly 200B parameters. Today is about treating that as a feature: routing a request to the right model for the job instead of sending everything to one general-purpose endpoint.
Objectives
- Register more than one local model endpoint with Hermes
- Understand the tradeoffs between a small fast model and a larger, slower one
- Route different kinds of prompts (quick lookup vs. multi-step reasoning) to different models
- Confirm routing behavior with real prompts against each backend
Lab: register and compare two local endpoints
Reconfigure Hermes with a second custom provider pointing at a different local model, then send the same one-shot prompt to each and compare latency and answer quality:
$ hermes config$ hermes -z "Summarize the tradeoffs between a 7B and a 30B parameter model in two sentences." --cliSession notes: to be filled in after the live session on Sep 30, 2026 — which two models we routed between, and what the actual latency/quality comparison looked like.